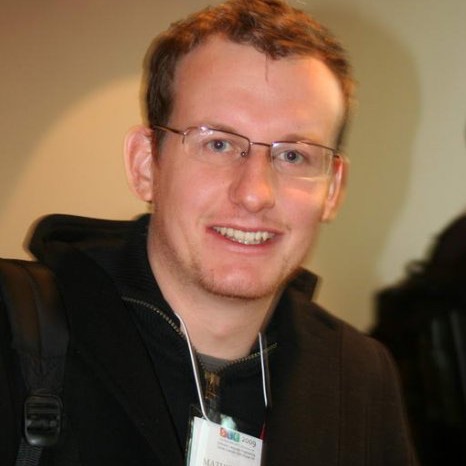
Portrait of Mathieu Acher

Mathieu Acher

Full Professor of Computer Science

Member of the Institut Universitaire de France (IUF)

I am a Full Professor of Computer Science at INSA Rennes, a member (sociétaire) of the Institut Universitaire de France (IUF), which each year recognizes a small number of French academics for the excellence of their research, and a researcher in the DiverSE team (Inria, IRISA, CNRS, Université de Rennes). I was appointed junior member of the IUF in 2021, on its then-new chair in science outreach (Médiation scientifique). Before joining INSA, I was Associate Professor at the University of Rennes 1 (2012–2022). In DiverSE, I lead the research axis on variability engineering. I co-lead the Inria challenge LLM4Code on reliable code assistants based on large language models, and the Inria–Simula associate team RIPOST on resilient and reproducible software. I am also strongly involved in FRAIME, the new Inria–Mitsubishi Electric challenge on trustworthy AI with formal methods, and in CodeCommons, a France 2030 project around Software Heritage, where I lead work package 2 and a team of nine engineers.

My research is about variability: software that comes in many variants and configurations, from the Linux kernel and video encoders to scientific pipelines and machine learning systems. I work on modelling, reverse engineering, testing, and learning these huge configuration spaces, and on what they mean for the reproducibility of science. I also study how large language models and coding agents change the way we build, migrate, and vary software, from legacy COBOL to chess engines written in a dozen programming languages.

I am also a chess player (FIDE Master, three international master norms), always up for a game of blitz. On my YouTube channel CodeplAI (in French), I explore AI, programming, and games: puzzles, algorithms, variants, and playing with and against AI.

News

  1. Paper at ASE 2026: Code Transformation Rule Synthesis Using LLMs: Potential and Limits, with Axel Allain, Aymeric Blot, and Djamel Eddine Khelladi (arXiv).
  2. Most Influential Paper Award at VARIABILITY 2026, the new conference merging SPLC, VaMoS, and ICSR, for Using Machine Learning to Infer Constraints for Product Lines (SPLC 2016), with Paul Temple, José A. Galindo, and Jean-Marc Jézéquel. I was also Journal-First co-chair.
  3. Paper accepted at NeurIPS 2026: Externalized CPDAG Summaries Improve LLM Causal Deduction, with my PhD student Wentao Sun (CIFRE with Nokia), João Paulo Nogueira, Dominique Verchère, and Alonso Silva (arXiv).
  4. Distinguished Paper Award at SCAM 2026 for CRACS: Question-Driven Assessment of Legacy Code Summaries in Industrial IBM-i Modernization, with N’Guessan Hermann Kouadio, Olivier Barais, and Jean-Marc Jézéquel, in collaboration with CGI France (HAL).
  5. Talk at the Semaine de l’IA of Université de Rennes: Langages de programmation à l’ère de l’IA générative : COBOL, M&M’s, français… ou peu importe ? (video, slides).
  6. Georges Aaron Randrianaina received the GDR SciLog 2026 thesis prize for Incremental, Reproducible Builds of Software Variants (news). Congratulations!
  7. Preprint: Do Programming Languages Still Matter to Your AI Coding Agent Teammate? Evidence at Scale from Chess Engines, with Jean-Marc Jézéquel: 34 engines, 17 languages, 2 coding agents (arXiv).
  8. Blog series on coding agents writing chess engines from scratch in Rust, C++, COBOL, Rocq, LaTeX (TeXCCChess), Brainfuck (BFChess), and more (overview).
Older news
  1. My panel The Constant, on the number 1070372 that has stayed unchanged in Stockfish’s source code since 2014, is part of the Source Code Exhibition for the 10th anniversary of Software Heritage, unveiled at UNESCO in Paris and since shown at the Cité des sciences and Sorbonne Université.
  2. JSS article: Piloting Copilot, Codex, and StarCoder2: Hot Temperature, Cold Prompts, or Black Magic? (DOI).
  3. Keynote at SBCARS (CBSoft 2025, Brazil): Software Variability for Replicable Science. Three papers at SPLC 2025 on neuroimaging pipelines, feature reduction and energy, and uniform sampling.
  4. Start of FRAIME (Formal Reasoning applied to AI for Methodological Engineering), a four-year Inria challenge with Mitsubishi Electric R&D Centre Europe on trustworthy AI with formal methods, in which I am strongly involved (press release).
  5. Teaching Reproducibility and Embracing Variability at ACM REP 2025, about my reproducibility course at INSA Rennes (blog post).
  6. Three papers at EASE 2025: a dataset of Linux kernel configurations at scale, LLM-based code customization, and JHipster performance.
  7. Two PhD defenses: Zohra Kaouter Kebaili on metamodel and code co-evolution, and Georges Aaron Randrianaina on incremental and reproducible builds of software variants.
  8. General chair of VaMoS 2025, the 19th International Working Conference on Variability Modelling of Software-Intensive Systems, in Rennes (4–6 February 2025).
  9. Distinguished Paper Award at ISSTA 2024 for our replicability study of MDPFuzz, with the Inria–Simula associate team RIPOST.
  10. Our experiments on large language models playing chess are featured in Monsieur Phi’s video ChatGPT rêve-t-il de cavaliers électriques ? (video, in French).
  11. Best Paper Award at AST 2024 for Testing for Fault Diversity in Reinforcement Learning (press release).
  12. Recommended for the CNRS bronze medal by Section 6 of the CNRS National Committee (Comité national de la recherche scientifique).
  13. Best Paper Award at MODELS 2023 for Experience in Specializing a Generic Realization Language for SPL Engineering at Airbus, with Airbus and McGill University.
  14. Luc Lesoil defended his PhD thesis, Deep Software Variability for Resilient Performance Models of Configurable Systems.
  15. The Handbook of Re-Engineering Software Intensive Systems into Software Product Lines is out (Springer): 20 chapters and 78 contributors on reverse engineering variability and re-engineering product lines and configurable systems.
  16. I am now Full Professor at INSA Rennes, still in Rennes and in the DiverSE team.
  17. Best Paper Award at ICSR 2022 (press release).
  18. Three papers at ICSE 2022: incremental build (research and NIER tracks) and transfer learning across Linux versions (journal first).
  19. Keynote on reproducible science and deep software variability, and two papers, at VaMoS 2022.
  20. Hugo Martin defended his PhD thesis, Machine Learning for Performance Modelling on Colossal Software Configuration Spaces.
  21. I defended my HDR, Modelling, Reverse Engineering, and Learning Software Variability (manuscript, video).
  22. Best Paper Award at SPLC 2021 (press release).
  23. Appointed junior member of the Institut Universitaire de France, starting October 2021 (announcement).

Research

Software comes in many variants. Configuration options, conditional compilation, plugins, generators, input data, and now prompts multiply the possible versions of a system, and each version can behave and perform differently. Variability makes it possible to tailor software to many needs, but it also creates combinatorial spaces that no one can fully test, configure, or understand by hand. My work is about modelling, reverse engineering, testing, and learning these spaces, and about the new forms of variability that large language models bring to software engineering.

AI and formal methods

Generative AI makes code cheap to produce but hard to trust. In FRAIME, a four-year Inria challenge with Mitsubishi Electric R&D Centre Europe started in 2025, we combine formal reasoning with machine learning: checking what AI produces, and letting AI help practitioners use formal methods. Two PhD theses started in DiverSE in 2026.

Deep variability and reproducible science

Results depend not only on software options but on inputs, compilers, libraries, operating systems, and hardware. This deep variability threatens the generalization of empirical results and the reproducibility of computational science, from neuroimaging pipelines to machine learning. I also teach reproducibility hands-on.

Modelling and reverse engineering variability

Feature models are the de facto standard for documenting what can vary. I have worked on their foundations, on languages and tools to compose, slice, compare, and reason about them (FAMILIAR, UVL), and on extracting them from code, configurators, and tables. This is the topic of my PhD and HDR.

Selected publications

All publications →

Papers with an award or that I consider representative. See also Google Scholar, DBLP, HAL, ORCID.

Browse all publications with abstracts and BibTeX →

Software

Agentic chess engines active

Chess engines written from scratch by coding agents (Claude Code, Codex) in 17+ languages, from Rust and Java to COBOL, Rocq, Lean, SQL, LaTeX (TeXCCChess), and Brainfuck (BFChess), with an Elo evaluation harness.

UVL Studio active

A self-contained web workbench for the Universal Variability Language: text editor, live checks, feature diagram, and SAT-based interactive configuration (source).

PlantUML Studio active

An offline, single-file PlantUML editor for teaching UML, with live well-formedness checks and “did you mean” diagnostics (source).

Programming languages catalog active

A catalog of 14,000+ programming languages merged from PLDB, Linguist, Pygments, Wikipedia, and Rosetta Code, with evidence from Software Heritage (CodeCommons project).

gptchess

Experiments pitting GPT models against Stockfish: Elo estimates and legal-move abilities of large language models (blog post).

FAMILIAR

A domain-specific language for managing feature models: compose, decompose, diff, refactor, configure, and reason about several feature models with SAT solvers and BDDs. Migrated to modern Java with a coding agent in 2026.

TuxML archived

Sampling, building, measuring, and learning Linux kernel configurations at scale (build failures, kernel size), including transfer learning across kernel versions (talk at ELC Europe 2019).

OpenCompare archived

Tools for product comparison matrices: editors, miners (MatrixMiner), visualizers, and configurators. No longer maintained, but we learned a lot.

Teaching

I teach software engineering, mostly at INSA Rennes in the computer science curriculum, and since 2024 I co-head the research Master SIF in Rennes (with Alexandre Termier). Recent courses:

  • Modelling, verification, advanced programming, and variability (CPOO1, 3rd year; CPOO2, 4th year): several formalisms to specify software (from class diagrams to feature models), to test it (JUnit, Mockito, mutation testing), and to vary it through time and space. Students apply them in Java, with design patterns, on the ChessBall project (student workspaces: CPOO1, CPOO2). Redesigned in 2026–27 along the lines of Carnegie Mellon’s 17-214 course, with a guided and critical use of AI coding assistants.
  • Reproducibility of computational experiments (4th and 5th year, since 2024): a hands-on course going from floating-point non-associativity, Docker, and continuous integration to reproducing and replicating published studies (LLMs playing chess, home advantage in football, energy of programming languages). See the ACM REP 2025 paper and the course repository.
  • Domain-specific languages (research Master SIF, Rennes; INSA Rennes since 2022): The Art of Domain-Specific Languages: Let’s Hack Our Own Languages! (materials, Langium demonstrators). At INSA, students develop DSLs for families of games, including services to play with AI and LLMs.

From 2012 to 2022, I taught at the University of Rennes 1 (ISTIC and ESIR): model-driven engineering, domain-specific languages, software development projects, software design and modelling, and Scala programming, and also at ENSAI. I was head of the Master 1 in Software Engineering at ISTIC, coordinator of the Bachelor (L3) internships and projects (2018–2021, 100+ students a year), in charge of teaching services at ISTIC (2014–2017), and a jury member of the Agrégation d’informatique (2022).

Beyond the classroom: lectures at the EJCP summer school for PhD students (2018, 2019, 2021, and 2023 on reproducible science and software engineering), a course on AI and sport for the M2 APAS and EOPS at the Université de Toulon (UFR STAPS, 2024–25), tutorials at ASE, SPLC, MODELS, and ECOOP/ECSA, and teaching.variability.io, a shared repository of teaching material on variability and configurable systems (see also the SPLTea workshops).

Outreach

I joined the IUF in 2021 on its then-new chair in science outreach (Médiation scientifique). Chess is my main way in: everyone knows the game, its rules give an objective referee, and it lets anyone check, rather than take on faith, what generative AI can and cannot do. My blog publishes these experiments with code and data.

Public talks are listed with the keynotes and invited talks.

I supervise PhD students, postdocs, and engineers in the DiverSE team, on variability, machine learning and LLMs for software engineering, reproducibility, and testing, often with industrial partners (CGI France, Sopra Steria, Nokia, Mitsubishi Electric, Airbus). I serve the software product line and variability community (SPLC, VaMoS, and VARIABILITY steering committees, VaMoS 2025 general chair), co-lead the Inria challenge LLM4Code and the Inria–Simula associate team RIPOST, and am strongly involved in the Inria–Mitsubishi Electric challenge FRAIME and the France 2030 project CodeCommons.

Theses

HDR (Habilitation à diriger des recherches) · 2021

Modelling, Reverse Engineering, and Learning Software Variability

University of Rennes 1, defended on 16 November 2021

Manuscript (HAL)Video of the defense
Abstract

Society expects software to deliver the right functionality, in a short amount of time and with fewer resources, in every possible circumstance whatever are the hardware, the operating systems, the compilers, or the data fed as input. For fitting such a diversity of needs, it is common that software comes in many variants and is highly configurable through configuration options, runtime parameters, conditional compilation directives, menu preferences, configuration files, plugins, etc. As there is no one-size-fits-all solution, software variability (“the ability of a software system or artifact to be efficiently extended, changed, customized or configured for use in a particular context”) has been studied the last two decades and is a discipline of its own. Though highly desirable, software variability also introduces an enormous complexity due to the combinatorial explosion of possible variants. For example, the Linux kernel has 15000+ options and most of them can have 3 values: “yes”, “no”, or “module”. Variability is challenging for maintaining, verifying, and configuring software systems (Web applications, Web browsers, video tools, etc.). It is also a source of opportunities to better understand a domain, create reusable artefacts, deploy performance-wise optimal systems, or find specialized solutions to many kinds of problems. In many scenarios, a model of variability is either beneficial or mandatory to explore, observe, and reason about the space of possible variants. For instance, without a variability model, it is impossible to establish a sampling strategy that would satisfy the constraints among options and meet coverage or testing criteria. I address a central question in this HDR manuscript: How to model software variability? I detail several contributions related to modelling, reverse engineering, and learning software variability.

I first contribute to support the persons in charge of manually specifying feature models, the de facto standard for modeling variability. I develop an algebra together with a language for supporting the composition, decomposition, diff, refactoring, and reasoning of feature models. I further establish the syntactic and semantic relationships between feature models and product comparison matrices, a large class of tabular data. I then empirically investigate how these feature models can be used to test in the large configurable systems with different sampling strategies. Along with this effort, I report on the attempts and lessons learned when defining the “right” variability language. From a reverse engineering perspective, I contribute to synthesize variability information into models and from various kinds of artefacts. I develop foundations and methods for reverse engineering feature models from satisfiability formulae, product comparison matrices, dependencies files and architectural information, and from Web configurators. I also report on the degree of automation and show that the involvement of developers and domain experts is beneficial to obtain high-quality models. Thirdly, I contribute to learning constraints and non-functional properties (performance) of a variability-intensive system. I describe a systematic process “sampling, measuring, learning” that aims to enforce or augment a variability model, capturing variability knowledge that domain experts can hardly express. I show that supervised, statistical machine learning can be used to synthesize rules or build prediction models in an accurate and interpretable way. This process can even be applied to huge configuration space, such as the Linux kernel one.

Despite wide applicability and observed benefits, I show that each individual line of contributions has limitations. I defend the following answer: a supervised, iterative process (1) based on the combination of reverse engineering, modelling, and learning techniques; (2) capable of integrating multiple variability information (eg expert knowledge, legacy artefacts, dynamic observations).

Finally, this work opens different perspectives related to so-called deep software variability, security, smart build of configurations, and (threats to) science.
Committee
  • Krzysztof Czarnecki (University of Waterloo, Canada), reviewer
  • Ina Schaefer (Technische Universität Braunschweig, Germany), reviewer
  • Romain Rouvoy (University of Lille, IUF, France), reviewer
  • Julia Lawall (Inria, France), examiner
  • Christian Kästner (Carnegie Mellon University, USA), examiner
  • Jean-Marc Jézéquel (University of Rennes 1, France), examiner

PhD thesis · 2011

Managing Multiple Feature Models: Foundations, Language, and Applications

University of Nice Sophia Antipolis, I3S laboratory (Modalis team). Supervised by Philippe Collet and Philippe Lahire

Manuscript (PDF)theses.frFAMILIAR
Abstract

Feature models (FMs) are a fundamental formalism for specifying and reasoning about commonality and variability of software product lines (SPLs). FMs are becoming increasingly complex, handled by several stakeholders or organizations, used to describe features at various levels of abstraction and related in a variety of ways. In different contexts and application domains, maintaining a single large FM is neither feasible nor desirable. Instead, multiple FMs are now used. In this thesis, we develop theoretical foundations and practical support for managing multiple FMs. We design and develop a set of composition and decomposition operators (aggregate, merge, slice) for supporting separation of concerns. The operators are formally defined, implemented with a fully automated algorithm and guarantee properties in terms of sets of configurations. We show how the composition and decomposition operators can be combined together or with other reasoning and editing operators to realize complex tasks. We propose a textual language, FAMILIAR (for FeAture Model scrIpt Language for manIpulation and Automatic Reasoning), which provides a practical solution for managing FMs on a large scale. An SPL practitioner can combine the different operators and manipulate a restricted set of concepts (FMs, features, configurations, etc.) using a concise notation and language facilities. FAMILIAR hides implementation details (e.g., solvers) and comes with a development environment. We report various applications of the operators and usages of FAMILIAR in different domains (medical imaging, video surveillance) and for different purposes (scientific workflow design, variability modeling from requirements to runtime, reverse engineering), showing the applicability of both the operators and the supporting language. Without the new capabilities brought by the operators and FAMILIAR, some analysis and reasoning operations would not be made possible in the different case studies.

Committee
  • Krzysztof Czarnecki, Associate Professor, University of Waterloo (Canada), reviewer
  • Jean-Marc Jézéquel, Professor, University of Rennes 1 (France), reviewer
  • Robert De Simone, Research Director, INRIA Sophia Antipolis (France), examiner
  • Patrick Heymans, Professor, University of Namur (Belgium), examiner
  • Robert B. France, Professor, Colorado State University (USA), examiner
  • Philippe Lahire, Professor, University of Nice Sophia Antipolis, supervisor
  • Philippe Collet, Associate Professor, University of Nice Sophia Antipolis, supervisor

Chess

I have been playing chess since I was 8. I discovered the game by chance in my home town, joined the Cannes chess club at 11, and had the chance to be trained by strong grandmasters there.

  • FIDE Master with three international master norms (2007, 2008, 2010), FIDE-rated since 1998
  • Twice French youth champion (1998, 2002)
  • Three World Youth Chess Championships (1998, 1999, 2002) and one European Youth Chess Championship (1998)
  • Second place in the French first league with the Cannes chess club (2003)
  • Gold medal in the French first league (board 6, 2009)

I no longer play at a high level, but I am always up for a blitz game online. Three of my games I like: a win against Santo-Roman (French first league, 2000), a win against Zhigalko (World Youth Championship, Greece, 2002), and a draw against Vachier-Lagrave (French first league, 2007).

Chess also shows up in my research and teaching:

  • How well do large language models play chess? Elo estimates and illegal moves of GPT models against Stockfish (gptchess, blog post), featured in Monsieur Phi’s video ChatGPT rêve-t-il de cavaliers électriques ? (YouTube, in French) and in a talk for school pupils at the Fête de la science 2025 (video, in French).
  • Chess engines written from scratch by coding agents in 17+ programming languages (overview, paper).
  • A replication study of metamorphic testing of chess engines (IST 2025) and a large-scale analysis of chess games with Stockfish (5 million games, 270 million positions).
  • Object-oriented design and testing courses at INSA Rennes built around the ChessBall project, and discussions about AlphaZero (video, in French).

Contact

The best way to reach me is by email: mathieu.acher@irisa.fr.

IRISA / Inria Rennes, Campus de Beaulieu, 35042 Rennes, France.